Numerical solution of DIVA / SSA
The DIVA and SSA momentum balances share the same 2D depth-integrated form: a nonlinear elliptic problem for the depth-averaged horizontal velocity \bar{\mathbf u} = (\bar u, \bar v), with coefficients (\mu, \beta_\mathrm{eff}) that depend on the solution. Yelmo discretises this problem on the Arakawa C-grid (the ac-grid) and linearises it by Picard iteration, freezing (\mu, \beta_\mathrm{eff}, H) at the previous iterate, solving a linear system for the new \bar{\mathbf u}, relaxing, and repeating until convergence.
Two solvers are provided for the linear step. Both produce the same solution at interior cells (the two systems are related by a sign and a cell-area factor), but they differ in the structure of the assembled matrix and in how boundary conditions are imposed. The choice is made at runtime via the parameter ydyn.ssa_solver = "energy" (default) or "residual", used by both the DIVA and the SSA Picard loops.
Discretisation conventions
Yelmo uses the Arakawa C / staggered AC grid:
- aa-nodes (cell centres): scalars — H, s, \bar\mu, \bar\mu\,H, \beta (before staggering).
- acx-nodes (right face of each aa-cell): \bar u, \tau_{d,x}, \beta_{\mathrm{eff},x}.
- acy-nodes (top face): \bar v, \tau_{d,y}, \beta_{\mathrm{eff},y}.
- ab-nodes (cell corners): cross-coupling viscosity (\bar\mu H)^{\mathrm{ab}}, zero if any of its four neighbouring aa-cells is on the ocean side (not fully ice covered, bed below sea level), so that a calving front carries no shear traction, and otherwise the average of \bar\mu\,H over the fully ice-covered neighbours (
stagger_visc_aa_ab), so that a land margin keeps its lateral shear.
The two unknowns per cell (\bar u at the right face and \bar v at the top face) are interleaved into a single state vector \mathbf x = [\,\bar u_{1}, \bar v_{1}, \bar u_{2}, \bar v_{2}, \dots\,], so the assembled linear system has dimension 2 N_\mathrm{cells}. The matrix is stored in CSR format and solved with LIS (Library of Iterative Solvers for Linear Systems); the iterative method and preconditioner are configured at runtime via ydyn.ssa_lis_opt_energy (default -i cg -p jacobi -maxiter 200 -tol 1.0e-2 -initx_zeros false) or ydyn.ssa_lis_opt_residual (default -i minres -p jacobi -maxiter 100 -tol 1.0e-2 -initx_zeros false), depending on ydyn.ssa_solver.
Per-row solver masks (ssa_mask_acx, ssa_mask_acy, set by set_ssa_masks) classify each ac-node as one of the values below. The masks and the thickness of the momentum balance come from the dynamic ice column (H_ice_dyn, f_ice_dyn): a cell with an ice fraction of at least A_FRONT_MIN = 0.1 is a full column with the effective thickness H_eff of the subgrid front, and a cell below 0.1 is ice free.
-1: prescribed velocity, kept at its current value;0: zero velocity (a face without a fully ice-covered neighbour, or a floating face against ice-free land);1: solved, grounded or grounding-line face;2: solved, floating face;3: ice-front face with the lateral boundary condition, a Neumann row driven by the depth-integrated lateral stress \tau_{l,\mathrm{int}} (with half of the basal drag in the energy assembler; the residual assembler imposes the stress condition as the row, without drag);4: ice-front face solved as an inner face, with half of the basal drag (only the ice half of its control area has drag).
Which front faces get the lateral boundary condition (3) and which are solved as inner faces (4) is set by ydyn.ssa_lat_bc (see DIVA).
The two assemblers share the same argument list, so they are interchangeable in the Picard loops of calc_velocity_diva and calc_velocity_ssa.
Residual assembler
The residual assembler (solver_ssa_ac.f90) builds a non-symmetric matrix A_\mathrm{res} and right-hand side \mathbf b_\mathrm{res} directly from the strong form of the SSA PDE. Writing N \equiv \bar\mu\,H for brevity, the interior \bar u row is a 5-point stencil in \bar u plus cross-coupling terms in \bar v on the neighbouring acy-faces, balanced against the basal drag and the driving stress. Schematically (cell (i,j), with N^{\mathrm{aa}} on aa-nodes and N^{\mathrm{ab}} on ab-nodes):
\sum_{(i',j')}\alpha^{x}_{i',j'}\,\bar u_{i',j'} \;+\; \sum_{(i',j')}\gamma^{xy}_{i',j'}\,\bar v_{i',j'} \;-\; \beta_\mathrm{eff}\,\bar u_{i,j} \;=\; \tau_{d,x}(i,j).
The \bar u stencil coefficients carry the membrane stretching and shearing,
\alpha^{x}_{i-1,j} \;=\; \tfrac{4}{\Delta x^{2}}\,N^{\mathrm{aa}}_{i,j},
\alpha^{x}_{i+1,j} \;=\; \tfrac{4}{\Delta x^{2}}\,N^{\mathrm{aa}}_{i+1,j},
\alpha^{x}_{i,j-1} \;=\; \tfrac{1}{\Delta y^{2}}\,N^{\mathrm{ab}}_{i,j-1},
\alpha^{x}_{i,j+1} \;=\; \tfrac{1}{\Delta y^{2}}\,N^{\mathrm{ab}}_{i,j},
with the centre coefficient \alpha^{x}_{i,j} being minus the sum of its four neighbours. The \gamma^{xy} coefficients couple the row to four neighbouring \bar v-faces via the \partial \bar v/\partial x and \partial \bar v/\partial y cross-terms in the membrane stress. The \bar v row has the analogous structure.
The right-hand side is the driving stress itself (no cell-area factor). The system A_\mathrm{res}\,\mathbf x = \mathbf b_\mathrm{res} is in general non-symmetric (through the Dirichlet rows and the front rows).
- Lateral / calving-front rows substitute the membrane-stress balance with the prescribed depth-integrated lateral stress \tau_{l,\mathrm{int}} in a row-specific stencil.
- Dirichlet rows replace the equation by \bar u_{i,j} = u^* with the corresponding column kept in place (non-symmetric).
- Free-slip, no-slip and periodic conditions are applied per side via the boundary-code helper
get_neighbor_indices_bc_codes.
Energy assembler (default)
The energy assembler (solver_ssa_ac_energy.f90) builds the Hessian of a discrete energy functional and solves K\,\mathbf x = \mathbf b for the velocity that minimises that energy. With (\mu, \beta, H) frozen during each Picard step the energy is quadratic, so K = \frac{\partial^{2} W}{\partial \mathbf x^{\,2}} is symmetric positive (semi-)definite and the linear step can use a symmetric Krylov method (CG by default).
Energy density
The continuum energy density underlying the SSA momentum balance is the sum of a membrane (deformation) term, a basal-drag term, and a gravitational potential-energy term:
\begin{aligned} W \;=\; \bar\mu\,H\,&\biggl( 2\!\left(\frac{\partial \bar u}{\partial x}\right)^{\!2} + 2\!\left(\frac{\partial \bar v}{\partial y}\right)^{\!2} + 2\,\frac{\partial \bar u}{\partial x}\,\frac{\partial \bar v}{\partial y} + \tfrac{1}{2}\!\left(\frac{\partial \bar u}{\partial y} + \frac{\partial \bar v}{\partial x}\right)^{\!2} \,\biggr) \\[4pt] &+\; \tfrac{1}{2}\,\beta\,(\bar u^{\,2} + \bar v^{\,2}) \;+\; \rho_i\,g\,H\,\!\left(\bar u\,\frac{\partial s}{\partial x} + \bar v\,\frac{\partial s}{\partial y}\right). \end{aligned}
The first line is 2\,\bar\mu\,H\,\dot{\bar\varepsilon}_e^{\,2} written out for the depth-averaged horizontal strain rates, including the vertical strain rate \dot\varepsilon_{zz} = -(\dot\varepsilon_{xx} + \dot\varepsilon_{yy}) from incompressibility. Stationarity of the integral \mathcal W = \int W \,\mathrm dx\,\mathrm dy with respect to (\bar u, \bar v) reproduces exactly the SSA / DIVA strong form, so any critical point of \mathcal W is a solution of the momentum balance.
Discrete assembly
Yelmo’s discrete energy is the cell-by-cell evaluation of W on the C-grid, with the derivatives \frac{\partial \bar u}{\partial x}, \frac{\partial \bar v}{\partial y}, \frac{\partial \bar u}{\partial y}, \frac{\partial \bar v}{\partial x} expressed as the natural finite differences between adjacent ac-nodes: membrane terms on aa-cells, shear terms on ab-corners, drag and driving terms on the ac-faces. K is assembled element by element from these terms: each cell or corner contributes a 4\times4 local Hessian over its four velocities, and each velocity is mapped to a matrix unknown before it is added (free, Dirichlet, tied to an inner unknown, or a ghost beyond the domain edge; see below). Since every entry comes from a local Hessian and a linear map, K is symmetric for any mask and boundary type. Each row gathers the terms of the elements around its unknown, so rows are assembled independently (in parallel with OpenMP). Inside the domain K has the same stencil graph as the residual matrix. At inner cells the two formulations are related by an exact algebraic identity (documented in the header of the energy assembler):
K_\mathrm{inner} \;=\; -\,A_\mathrm{res, inner}\cdot \Delta x\,\Delta y, \qquad \mathbf b_\mathrm{inner} \;=\; -\,\boldsymbol\tau_d \cdot \Delta x\,\Delta y.
So the energy formulation is, at interior cells, the residual formulation rescaled by the cell area and a sign — the physical solution at interior cells is identical to machine precision. Where the two solvers differ is at boundaries:
- Lateral / calving-front BC: the front stress enters the energy as a boundary-work term \pm\,\tau_{l,\mathrm{int}}\,\Delta y on the RHS, with the sign determined by the outward normal. This is the variational form of the Neumann condition and is symmetric by construction. It replaces the driving stress in front rows: there \tau_d is taken across the ice front (H/2 times the surface jump), so \tau_d\,\Delta x\,\Delta y is the same front force, and keeping both would apply it twice.
- Free-slip domain edges: the edge unknown is tied to its inner neighbour (u_\mathrm{edge} = u_\mathrm{inner}, as in the residual solver) and folded into its row, K_\mathrm{red} = T^\mathsf{T} K T, which keeps K symmetric. The edge cell’s own membrane and shear terms are kept in the folded row (the residual solver drops them), so the two solvers differ in the edge row of cells. After the solve the edge unknown takes its root’s value (
lgs%copy_from). Velocities one cell beyond an edge are periodic wraps, copies of the edge value (free-slip) or zero (no-slip). - Dirichlet rows: prescribed values (ice-free faces,
ssa_mask = -1, no-slip edges) are imposed by static condensation — the column is multiplied by the known velocity and moved to the RHS — instead of by row replacement. This preserves the symmetry of K and so allows CG / AMG to be used without spoiling the SPD structure.
The viscosity staggering aa \to ab is the same routine (stagger_visc_aa_ab) used by the residual assembler.
Why bother?
Two practical advantages flow from the SPD structure:
- Linear solver choice: CG (optionally with an algebraic multigrid preconditioner) is typically faster and more robust than non-symmetric Krylov methods for large SPD systems, and converges monotonically in the energy norm.
- Physical interpretability and discrete consistency: every term in K and \mathbf b corresponds to a contribution to a discrete energy. Boundary conditions that are natural for the continuum functional (e.g. Neumann front stress) become natural for the discrete one. This makes it easier to add new physics — e.g. alternative friction laws, additional body forces — in a way that provably preserves the variational structure.
The Picard loop, the viscosity update, the F-integral closure and the basal-stress and 3D velocity diagnostics are identical between the two solvers: only the linear-system assembly differs.
Velocity limit
Yelmo bounds the depth-averaged velocity of the SSA and DIVA solvers, since a runaway velocity solution would otherwise end the run (e.g., during a thermally driven ice-stream activation). The method is set by ydyn.ssa_vel_lim_method = "drag" | "clip", and the limit by ydyn.ssa_vel_max (default 10 000 m/yr). The run is stopped by yelmo_check_kill once any depth-averaged speed reaches 2\,u_\mathrm{max}, with u_\mathrm{max} = ssa_vel_max (see Time stepping).
"clip"
After every linear solve inside the Picard loop, each velocity component is clipped to [-u_\mathrm{max}, u_\mathrm{max}] (ssa_vel_clip). The clipped velocity is not a solution of the momentum balance, and the Picard map becomes non-smooth at the edge of the clipped region. The viscosity and friction of the next iteration are evaluated from the clipped velocity, which is too slow, so the next solve falls below the limit and the one after overshoots it again. Picard therefore cycles instead of converging when many cells reach the limit, and the time step can collapse to dt_min (see the test below).
"drag" (default)
The limit is imposed through an additional drag in the linear system, so that each Picard iteration solves a smooth, modified momentum balance. On every free face, the limit drag is defined as a function of the face speed s:
\tau_\mathrm{lim}(s) = \tau_c\,x^2, \qquad x = \max\left(0, \frac{s - s_0}{u_\mathrm{max} - s_0}\right),
where \tau_c = ssa_vel_lim_tau (default 10^5 Pa) is the drag at s = u_\mathrm{max} and s_0 = 0.8\,u_\mathrm{max} is the onset speed (a fixed constant, vel_lim_f_s0). Both \tau_\mathrm{lim} and its derivative vanish at s_0, so the solution below 0.8\,u_\mathrm{max} is identical to the unlimited one. The drag acts on all free faces (ssa_mask = 1–4): grounded, floating and ice-front faces. At front faces (ssa_mask = 3, 4) it has the same weight 1/2 as the basal friction, since only the ice half of the face’s control area has drag. The speed at an acx-face is computed with \bar v averaged from the four neighbouring acy-faces, and vice versa.
The limit drag is Newton-linearised around the current Picard iterate \bar u^0, for the face’s own component with the cross component held fixed:
\tau_{\mathrm{lim},x}(\bar u) \approx \tau_{\mathrm{lim},x}(\bar u^0) + k\,(\bar u - \bar u^0), \qquad k = b\left(1 - \frac{\bar u^2}{s^2}\right) + \tau_\mathrm{lim}'(s)\,\frac{\bar u^2}{s^2},
where b = \tau_\mathrm{lim}/s. A Picard (secant) linearisation b\,\bar u, as used for the basal friction, would oscillate for this steep drag. Since k \ge 0, adding it to the friction keeps the matrix symmetric positive definite. calc_vel_lim_drag returns k and the offset r = (k - b)\,\bar u^0 per face, so that \tau_{\mathrm{lim},x} \approx k\,\bar u - r. The assemblers add k to the matrix friction and r to the right-hand side, with the face weight of the friction. The basal stress \tau_b, the basal velocity and the frictional heating are computed from the physical friction only, so the limit drag does not heat the bed.
After each solve, the velocity components are also clipped to [-u_\mathrm{max}, u_\mathrm{max}] (ssa_vel_clip), as with "clip". A converged drag solution stays near 0.8–0.85\,u_\mathrm{max}, so the clip does not change it; it bounds the iterates that the drag does not hold. Below s_0 the drag is zero, so ice that nothing else holds (e.g. a floating fragment with no friction and no shear coupling to other ice) can reach many times u_\mathrm{max} in one solve, and the Newton steps of the drag then need more Picard iterations than ssa_iter_max to bring it back. In the “residual” assembler, the rows of lateral-bc front faces (ssa_mask = 3) impose the front stress condition and have no drag term, so there the clip is the only limit.
The front faces need the limit as much as the grounded interior. At coarse resolution, thick front cells can be driven to runaway speeds, e.g. thick, barely floating front cells on a 32 km Antarctic grid, or a grounded cliff with a large freeboard at the Helheim front (8 km) or at Jakobshavn (4 km).
The number of faces where the limit acts after the last Picard iteration (drag above s_0, or clipped) is written as ssa_lim_n to timesteps.nc (yelmo.log_timestep), and yelmo_update logs the number of steps with an active limit and the maximum face count. A run that leans on the limit is therefore visible, rather than silently capped.
Note that the speed settles near 0.8–0.85\,u_\mathrm{max}, not at u_\mathrm{max}, since a small drag (about 10 kPa in TROUGH-F17) is enough to stop the runaway. Thus ssa_vel_max should be set about 20 % above the intended maximum speed.
Test: TROUGH-F17
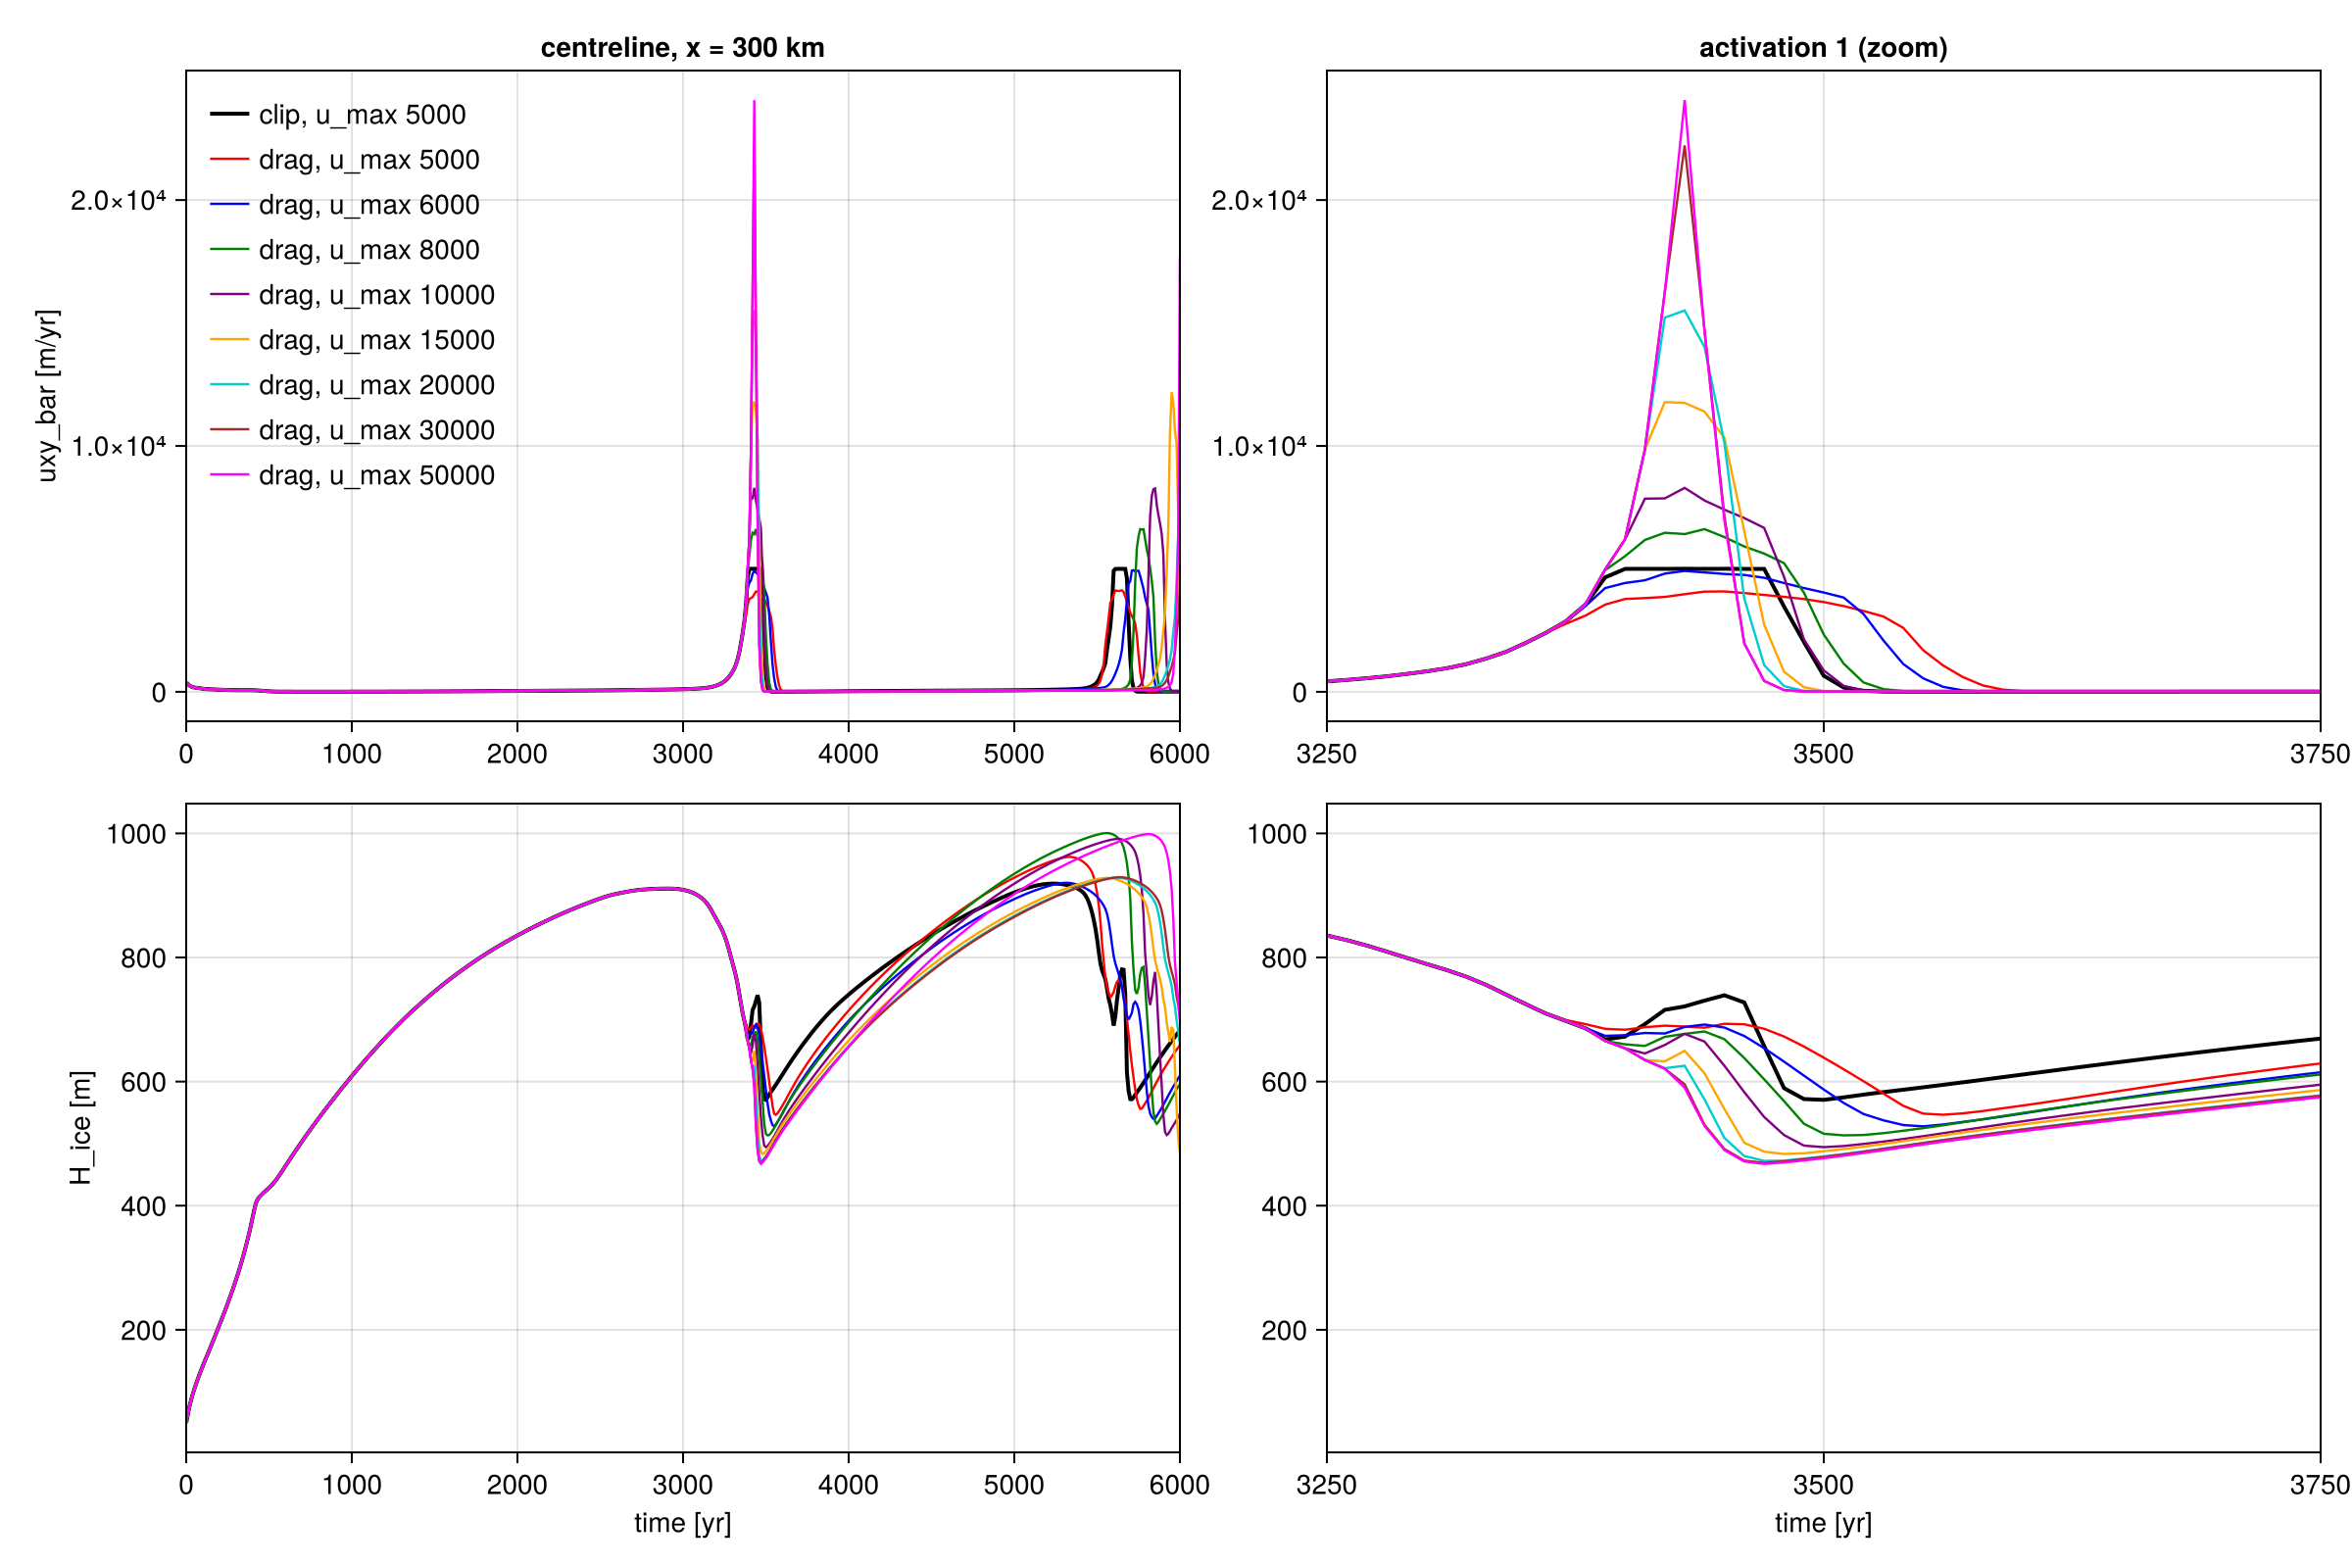
"clip" (ssa_vel_max = 5000 m/yr) and "drag" for ssa_vel_max from 5000 to 50 000 m/yr. Right: zoom on activation 1.The thermally driven activations of TROUGH-F17 (about every 2.2 kyr) were run with both methods (DIVA, energy solver, 4 km). With ssa_vel_max = 5000 m/yr, the drag removes the convergence failure (Table 1).
0–8 kyr, ssa_vel_max = 5000 m/yr |
"clip" |
"drag" |
|---|---|---|
time steps (steps at dt_min) |
9957 (1161) | 4802 (5) |
| activation 1: median dt | 0.016 yr | 0.42 yr |
| activation 1: mean Picard iterations | 14.9 | 6.4 |
activation 1: solves at ssa_iter_max |
51 % | 0 % |
| activation 1: median pc_eta | 1.0e-2 | 2.2e-4 |
All runs oscillate in the same way, with the first activation at about 3420–3450 yr (Figure). Below about 15 000 m/yr, the peak speed at x = 300 km is set by the limit, at about 0.8\,u_\mathrm{max} (e.g., 4900 m/yr for 6000 m/yr and 8300 m/yr for 10 000 m/yr). For larger limits, the peak converges to about 24 000 m/yr (30 000 and 50 000 m/yr), which is the unlimited surge of this setup. A lower limit gives a longer, weaker surge with less thinning, and a shorter cycle (activation 2 at about 5650 yr for 5000 m/yr and 5950 yr for 15 000 m/yr). With "clip", the ice at x = 300 km thickens while the velocity is held at the limit, since ice keeps arriving from upstream. This does not occur with "drag", which shows that the clip also changes the thickness evolution of the surge. The TROUGH-F17 parameter file uses ssa_vel_max = 50 000 m/yr, so that the surge is not limited. The scripts and run list are in analysis/vel-lim/.